

rewrite this content and keep HTML tags as is. This is content from rss feed and I don’t need their *Daily Debrief Newsletter*, their tags from bottom like this *Share this articleCategoriesTags*, Editorial Process section, phrases like *Featured image from Peakpx, chart from Tradingview.com*, SPECIAL OFFERS and similar sections – just remove such sections and save only article itself:
DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit that this is the official release superseding the preview, and that the architecture and size are unchanged. The gains come from re-post-training, not a new design.
The checkpoint ships with the DSpark speculative decoding module attached, matching the structure of DeepSeek-V4-Flash-DSpark. Hugging Face reports 304B parameters for the repo, which includes that draft module on top of the 284B base.
On the API side, deepseek-v4-flash now natively supports the Responses API format and is adapted for Codex. The V4-Pro API and the app and web models were not updated.
Is it deployable?
Yes, in two very different ways.

Via API, it is deployable by almost anyone: DeepSeek’s pricing page lists deepseek-v4-flash at $0.14 per 1M input tokens on a cache miss, $0.0028 on a cache hit, and $0.28 per 1M output tokens, with a 2,500 concurrency limit. That is roughly a third of deepseek-v4-pro output pricing ($0.87). Seed-stage startups, indie developers, and internal platform teams can run agent loops at this price without a GPU budget.
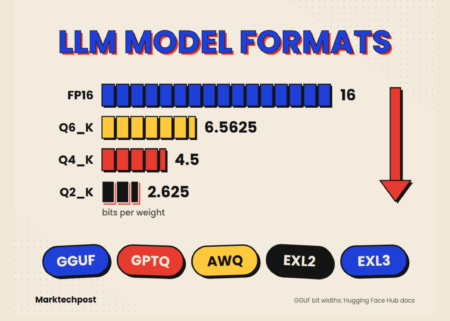
Via self-hosting, the bar is much higher: The weights are MIT-licensed and ungated, but every expert stays resident in memory even though only 13B activate per token. DeepSeek’s vLLM example serves it on a single 4×GB300 node. Unsloth’s dynamic GGUFs put the lossless 8-bit build at 162 GB and a 3-bit build at 103 GB, needing roughly 110 GB of combined RAM plus VRAM. Self-hosting suits mid-size and large enterprises with a serving cluster, or one well-specced workstation at aggressive quantization.
Architecture
Per the DeepSeek-V4 technical report, V4-Flash is a 284B-parameter MoE with 13B activated per token and a 1M-token context window. Each MoE layer holds 1 shared expert and 256 routed experts with an intermediate dimension of 2048, and 6 routed experts fire per token. The first three MoE layers use hash routing. Multi-token prediction depth is 1.
Attention is hybrid, combining Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA). Manifold-Constrained Hyper-Connections (mHC) replace conventional residual connections, with expansion factor 4 and 20 Sinkhorn-Knopp iterations. Pre-training used more than 32T tokens and the Muon optimizer. The paper’s headline efficiency figure — 27% of single-token inference FLOPs and 10% of KV cache versus DeepSeek-V3.2 at 1M context — is stated for V4-Pro, not Flash.
r) return 0;
if (mode === ‘dense’) return 1;
if (mode === ‘csa’){
if (c >= r-1) return 1; /* local window */
if (Math.floor(c/4) === 0) return 1; /* sink block */
return ((r + Math.floor(c/4)) % 3 === 0) ? 2 : 0;
}
if (c >= r) return 1;
return (c % 5 === 0) ? 2 : 0;
}
function drawAtt(mode){
curAtt = mode;
if (attTimer) clearInterval(attTimer);
for (var i=0;i= N){ clearInterval(attTimer); attTimer = null; return; }
for (var c=0;c’ + lit + ”;
}
var attBtns = document.querySelectorAll(‘[data-att]’);
for (var a=0;a= 1000) return ‘$’ + Math.round(x).toLocaleString();
if (x >= 100) return ‘$’ + x.toFixed(0);
return ‘$’ + x.toFixed(2);
}
function calc(){
var inM = +document.getElementById(‘rIn’).value;
var outM = +document.getElementById(‘rOut’).value;
var hit = +document.getElementById(‘rHit’).value / 100;
document.getElementById(‘vIn’).textContent = inM;
document.getElementById(‘vOut’).textContent = outM;
document.getElementById(‘vHit’).textContent = Math.round(hit*100);
function cost(p){
return inM*hit*p.hit + inM*(1-hit)*p.miss + outM*p.out;
}
var f = cost(P.flash), pr = cost(P.pro);
document.getElementById(‘cFlash’).textContent = money(f);
document.getElementById(‘cPro’).textContent = money(pr);
document.getElementById(‘cSave’).textContent = money(pr – f);
document.getElementById(‘cPct’).textContent = pr > 0 ? Math.round((1 – f/pr)*100) + ‘% cheaper’ : ‘\u2014’;
var mx = Math.max(f, pr) || 1;
document.getElementById(‘cb1’).style.width = (f/mx*100) + ‘%’;
document.getElementById(‘cb2’).style.width = (pr/mx*100) + ‘%’;
document.getElementById(‘cbv1’).textContent = money(f);
document.getElementById(‘cbv2’).textContent = money(pr);
}
var rs = [‘rIn’,’rOut’,’rHit’];
for (var s=0;s