Close Menu
    Facebook X (Twitter) Instagram
    • Privacy Policy
    • Terms Of Service
    • Social Media Disclaimer
    • DMCA Compliance
    • Anti-Spam Policy
    Facebook X (Twitter) Instagram
    Fintech Fetch
    • Home
    • Crypto News
      • Bitcoin
      • Ethereum
      • Altcoins
      • Blockchain
      • DeFi
    • AI News
    • Stock News
    • Learn
      • AI for Beginners
      • AI Tips
      • Make Money with AI
    • Reviews
    • Tools
      • Best AI Tools
      • Crypto Market Cap List
      • Stock Market Overview
      • Market Heatmap
    • Contact
    Fintech Fetch
    Home»AI News»NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands
    NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands
    AI News

    NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands

    August 19, 20263 Mins Read
    Share
    Facebook Twitter LinkedIn Pinterest Email
    kraken

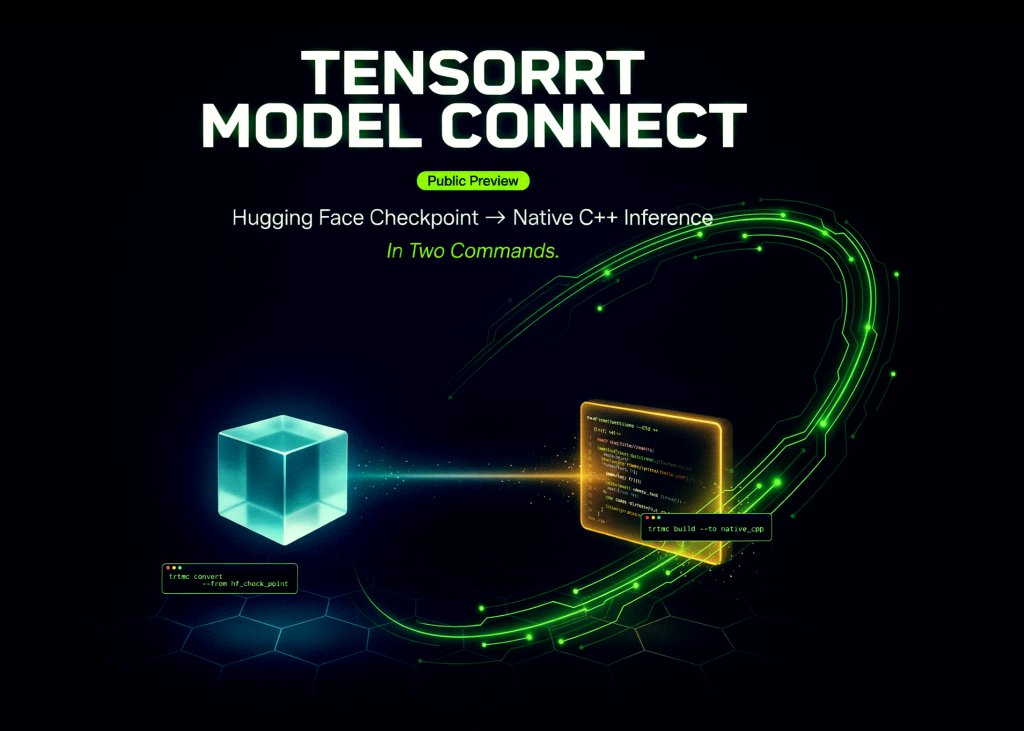
    NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an open-source project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands. There is no intermediate ONNX export step. The build produces a versioned .bundle artifact that runs through native C++ task APIs, so inference can execute in a C++ service, embedded application, or robotics stack without PyTorch in the runtime path. The project is Apache-2.0 licensed and ships as a collection of family-owned reference implementations rather than a single generic converter. NVIDIA also states that the entire project — model implementations, performance tuning, tests, integrations, and docs — was built using OpenAI Codex agents under human direction and review.

    Is it deployable?

    Yes, for evaluation and native integration work, with real conditions. The code is open and installable. Release wheels currently target Linux aarch64 only, with Python 3.10 or 3.12, glibc 2.39 or newer, and TensorRT 11.1.0.106. x86_64 wheels are not published; x86_64 users must take the Docker source-build path.

    • Company level: Best fit today is teams that already own their inference stack: NVIDIA-shop startups, robotics and device companies, and platform or inference teams inside mid-size and large enterprises. Small teams shipping a Python service get less from it. Regulated enterprises should wait for a tagged release before standardizing on it.
    • Industries: Robotics and autonomous machines, industrial inspection and manufacturing, automotive in-vehicle compute, medical devices, defense and aerospace edge systems, and media processing — anywhere inference has to live inside a C++ binary rather than a Python server.
    • Applications: On-device text generation, speech recognition and synthesis, OCR and document parsing, embeddings and reranking for a retrieval service written in C++, diffusion image and video generation, segmentation, and time-series forecasting.

    The two commands

    The quick start builds and runs Qwen3-0.6B:

    trtmc build Qwen/Qwen3-0.6B –precision bf16 –max-cache-length 16384 –output qwen3-0.6b.bundle
    trtmc run ./qwen3-0.6b.bundle –prompt “What is the capital of France? Answer in one word.” –chat-template –no-thinking

    The same .bundle loads from C++ with trtmc::load(“./qwen3-0.6b.bundle”).

    binance

    The bundle is the actual design decision

    TRTMC splits build and runtime at a versioned artifact. Python owns checkpoint resolution and TensorRT engine construction. Native profiles then execute inference in C++ without PyTorch. A small number of hybrid profiles invoke a helper Python executable, and their manifests declare that dependency explicitly.

    Applications call task APIs — generate(), transcribe(), generate_image(), embed(), solve() — instead of maintaining conversion stages and per-model application glue. trtmc inspect exposes bundle kind, model family, precision, runtime identity, and engines, which makes the artifact auditable rather than opaque.

    NVIDIA frames the conventional route as PyTorch → ONNX or TorchScript → TensorRT → model-specific C++ integration, and names the failure modes it removes: export gaps, repeated per-model integration, and validation spread across several conversion artifacts.

    Key Takeaways

    • Two commands take a supported Hugging Face checkpoint to native C++ TensorRT inference, with no ONNX step.
    • A versioned .bundle is the handoff between the Python build and a PyTorch-free C++ runtime.
    • The July 29, 2026 GB300 snapshot covers 105 profiles across 76 families; 102 beat their declared reference by more than 5%.
    • Wheels are Linux aarch64 only today; x86_64 requires the Docker source build.
    notion
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    Fintech Fetch Editorial Team
    • Website

    Related Posts

    Google DeepMind's WeatherNext 3 Trains on Weather Station Observations to Deliver 5 km Global Forecasts, Refreshed Every Hour

    Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver 5 km Global Forecasts, Refreshed Every Hour

    September 4, 2026
    From MIT to IBM, expediting AI and quantum deployment | MIT News

    From MIT to IBM, expediting AI and quantum deployment | MIT News

    September 3, 2026
    Gatik raises $200M to scale AI-powered autonomous freight

    Gatik raises $200M to scale AI-powered autonomous freight

    September 1, 2026
    OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI Startup, and One Trust Boundary Per Gateway

    OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI Startup, and One Trust Boundary Per Gateway

    August 31, 2026
    Add A Comment

    Comments are closed.

    Join our email newsletter and get news & updates into your inbox for free.


    Privacy Policy

    Thanks! We sent confirmation message to your inbox.

    kraken
    Latest Posts
    Google DeepMind's WeatherNext 3 Trains on Weather Station Observations to Deliver 5 km Global Forecasts, Refreshed Every Hour

    Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver 5 km Global Forecasts, Refreshed Every Hour

    September 4, 2026
    Make Money Online with Claude AI Agent— Here's How I Did It

    Make Money Online with Claude AI Agent— Here’s How I Did It

    September 4, 2026
    Complete Claude Ecosystem - AI, Code, Cowork, M365 & Certification Udemy Course

    Complete Claude Ecosystem – AI, Code, Cowork, M365 & Certification Udemy Course

    September 4, 2026
    How Andrej Karpathy ACTUALLY Uses AI (10x Faster)

    How Andrej Karpathy ACTUALLY Uses AI (10x Faster)

    September 4, 2026
    7 Stocks I’m Buying HEAVY Right Now September 2026

    7 Stocks I’m Buying HEAVY Right Now September 2026

    September 4, 2026
    coinbase
    LEGAL INFORMATION
    • Privacy Policy
    • Terms Of Service
    • Social Media Disclaimer
    • DMCA Compliance
    • Anti-Spam Policy
    Top Insights
    Terence Zimwara

    Bitcoin Surges Past $82K Following Significant Short Liquidations

    September 4, 2026
    Remixpoint Cuts ETH, XRP Exposure After Market Review, Keeps 1,506 BTC in Treasury

    Remixpoint Reduces ETH and XRP Holdings Post-Market Analysis, Retains 1,506 BTC in Reserves

    September 4, 2026
    coinbase
    Facebook X (Twitter) Instagram Pinterest
    © 2026 FintechFetch.com - All rights reserved.

    Type above and press Enter to search. Press Esc to cancel.