Close Menu
    Facebook X (Twitter) Instagram
    • Privacy Policy
    • Terms Of Service
    • Social Media Disclaimer
    • DMCA Compliance
    • Anti-Spam Policy
    Facebook X (Twitter) Instagram
    Fintech Fetch
    • Home
    • Crypto News
      • Bitcoin
      • Ethereum
      • Altcoins
      • Blockchain
      • DeFi
    • AI News
    • Stock News
    • Learn
      • AI for Beginners
      • AI Tips
      • Make Money with AI
    • Reviews
    • Tools
      • Best AI Tools
      • Crypto Market Cap List
      • Stock Market Overview
      • Market Heatmap
    • Contact
    Fintech Fetch
    Home»AI News»Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak
    Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak
    AI News

    Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak

    September 29, 20263 Mins Read
    Share
    Facebook Twitter LinkedIn Pinterest Email
    synthesia

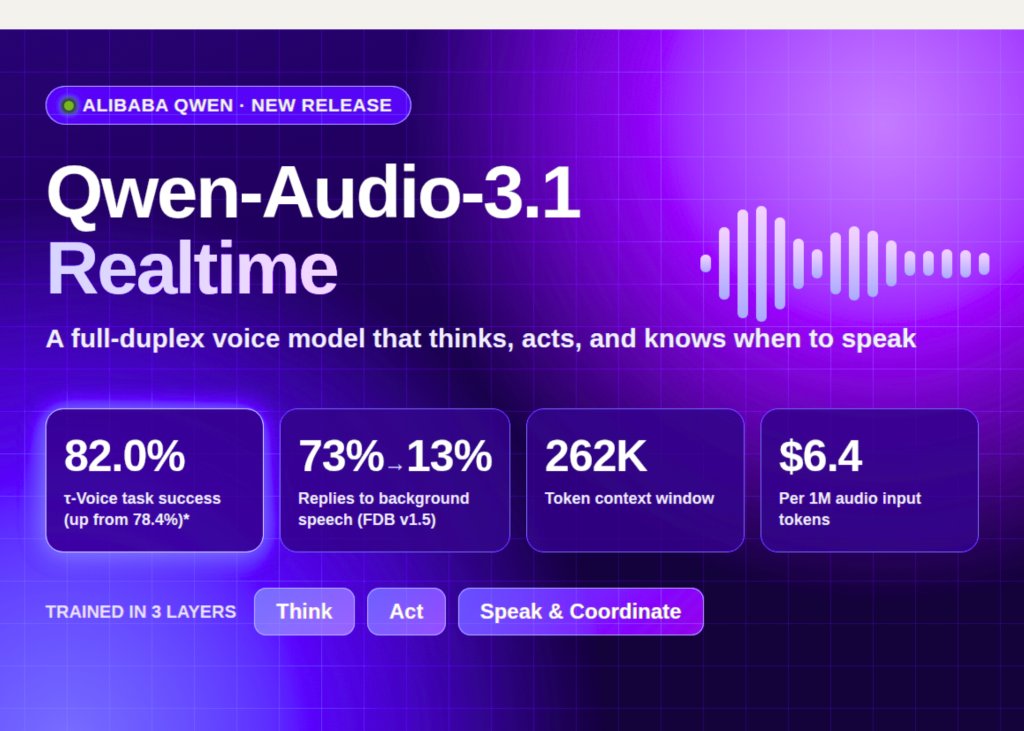
    Alibaba’s Qwen team has released Qwen-Audio-3.1, a 5-model audio stack spanning ASR, TTS and realtime interaction. The main model is Qwen-Audio-3.1-Realtime, a full-duplex speech model built for voice agents that call tools. Qwen also cut prices: about 85% on Realtime, about 70% on TTS and up to 95% on ASR.

    Is it deployable? Yes, as a managed API. qwen-audio-3.1-realtime-plus is live on QwenCloud over WebSocket. No open weights were announced.

    What Ships on QwenCloud

    The model page lists text and audio as both input and output. Context is 262K tokens, with 245K max input and 16K max output. Default limits are 60 requests and 100K tokens per minute. Pricing is $6.4 per 1M audio input tokens and $0.8 per 1M text input tokens. Text and audio output costs $24 per 1M tokens, with output text not charged. Key features include function calling, web search, structured outputs, context cache and fine-tuning.

    A companion model, Qwen-Audio-3.1-ASR-Flash-Filetrans, targets offline long-audio transcription. It supports hot words, speaker separation, punctuation and multilingual plus Chinese dialect recognition. It costs $0.15 input and $0.47 output per 1M tokens.

    Architecture: 2 Models Behind 1 Voice

    The system runs 2 models with the same Audio Encoder and LLM design. A full-duplex decision model predicts whether to keep listening, speak, stop or resume. A speech-to-text model writes the response content as text. A context-aware voice renderer then turns that text into streaming speech. It conditions on conversation history, voice cues and acoustic context.

    livechat

    Training is organized into 3 layers: Think, Act, and Speak and Coordinate.

    Think: M²-OPD

    Core-Cocktail SFT re-anchors the audio model to its source text LLM using million-hour-scale paired data. Multimodality OPD follows. A Text Teacher and a frozen Audio Reference score each token of the student’s own trajectory. This is on-policy distillation, not imitation of pre-written answers. Domain experts for empathy, pragmatic intent and acoustic scenes are then trained with GRPO. Multi-Teacher OPD merges them into 1 deployable model.

    Act: Executable Environments

    Each training domain bundles a tool pool, a stateful JSON database and a natural-language business policy. Domains are seeded from open-source tool and MCP server definitions. Every task defines 1 of 3 outcomes: a write, a justified refusal, or an unsupported request. Scoring checks terminal state, then permitted writes, then behavioral assertions. A fluent reply cannot rescue a failed state check.

    GRPO receives rewards at dialogue, milestone and turn level. Search training penalizes redundant queries with rquery=qmin⁡(1,nrefnpred)r_{\text{query}} = q \min \left( 1, \frac{n_{\text{ref}}}{n_{\text{pred}}} \right). Mean queries per search call fell from 4.37 to 1.05. Trigger F1 slipped from 60.87% to 58.61%.

    Speak and Coordinate

    This layer decides whether, when and how to speak. On Full-Duplex-Bench v1.5, replies to people talking to someone else fell from 0.13 to 0.03. On v3.0, the filler rate dropped from 0.7590 to 0.2960. There are trade-offs. After interruptions, the unwanted resume rate rose from 0.035 to 0.130. Interruption stop latency is 1.116 seconds, versus 0.383 for GPT-Realtime-2.

    Interactive Explainer

    Explore the Think, Act, Speak loop, duplex decisions, a scored training episode and the search reward.

    =sc.length-1){stopPlay();return}step()},2400);this.textContent=”Pause”}

    ledger
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    Fintech Fetch Editorial Team
    • Website

    Related Posts

    Using AI to mitigate the growing environmental threat of data centers | MIT News

    Using AI to mitigate the growing environmental threat of data centers | MIT News

    October 11, 2026
    ◀

    NVIDIA PivotOPD Teaches Multi-Turn AI Agents to Recover From Pivotal Mistakes

    October 10, 2026
    3 Questions: What is the best path forward for AI in academia? | MIT News

    3 Questions: What is the best path forward for AI in academia? | MIT News

    October 9, 2026
    What Happens When a Trusted Model Repo Changes? Unsloth Studio Re-Checks Before It Runs

    What Happens When a Trusted Model Repo Changes? Unsloth Studio Re-Checks Before It Runs

    October 8, 2026
    Add A Comment

    Comments are closed.

    Join our email newsletter and get news & updates into your inbox for free.


    Privacy Policy

    Thanks! We sent confirmation message to your inbox.

    bybit
    Latest Posts
    Has AI Solved Reverse Engineering?

    Has AI Solved Reverse Engineering?

    October 11, 2026
    Cointelegraph

    Meanwhile secures additional funding.

    October 11, 2026
    AI for Absolute Beginners — The 5-Minute Starter Guide

    AI for Absolute Beginners — The 5-Minute Starter Guide

    October 11, 2026
    Bitcoin Price Holds $82K as Blackrock Leads ETF Rebound

    Bitcoin Remains Steady at $82K as Blackrock Drives ETF Recovery

    October 10, 2026
    Tokenized stock dividend onchain reinvestment

    Sui and Alibaba Cloud Aim for AI Agents to Cover Their Cloud Expenses with Stablecoins

    October 10, 2026
    bybit
    LEGAL INFORMATION
    • Privacy Policy
    • Terms Of Service
    • Social Media Disclaimer
    • DMCA Compliance
    • Anti-Spam Policy
    Top Insights
    Bitcoin companies are learning that holding forever takes cash

    Bitcoin firms are discovering that long-term holding requires liquidity.

    October 11, 2026
    Bitcoin.com News

    Chinese Communist Party Advocates for a Nationwide Blockchain Infrastructure

    October 11, 2026
    aistudios
    Facebook X (Twitter) Instagram Pinterest
    © 2026 FintechFetch.com - All rights reserved.

    Type above and press Enter to search. Press Esc to cancel.