Prime Intellect has launched Prime Inference, a serving platform for frontier open-source models. It offers serverless endpoints and reserved capacity on Prime’s own GPUs across multiple datacenters. Before public release, it processed nearly a trillion tokens per day internally. That traffic came from RL rollouts, synthetic data generation, evaluations and long-running coding agents.
What is Prime Inference?
Prime Inference is the serving layer of Prime Intellect’s open training stack. The company already ships post-training tools such as prime-rl, verifiers and sandboxes. Serving closes that loop: deployed models generate production traces that can feed back into training. Prime reports its GLM-5.3 endpoint ranks among the fastest on OpenRouter. It also cites a near-zero tool-call error rate and 100% uptime since launch.
- Two modes: serverless endpoints for variable demand, reserved capacity for sustained workloads.
- OpenAI compatible: point any OpenAI SDK at https://api.pinference.ai/api/v1 (docs).
- Uptime: automatic failover across datacenters routes traffic to healthy deployments.
- Hardware: NVIDIA Blackwell today, with Vera Rubin listed as coming soon.
- Billing: unified billing with team-level usage tracking. Per-model pricing is not yet fully published in the docs.
How the serving stack works
The stack combines NVIDIA Dynamo, vLLM, Mooncake and FlashInfer. It was built with Inferact and NVIDIA, and fixes are contributed upstream.
The target workload is agentic. A typical agent turn adds about 6K tokens to a 140K-token prompt. Prime benchmarks this mix with SemiAnalysis AgentX, and injected cold arrivals.
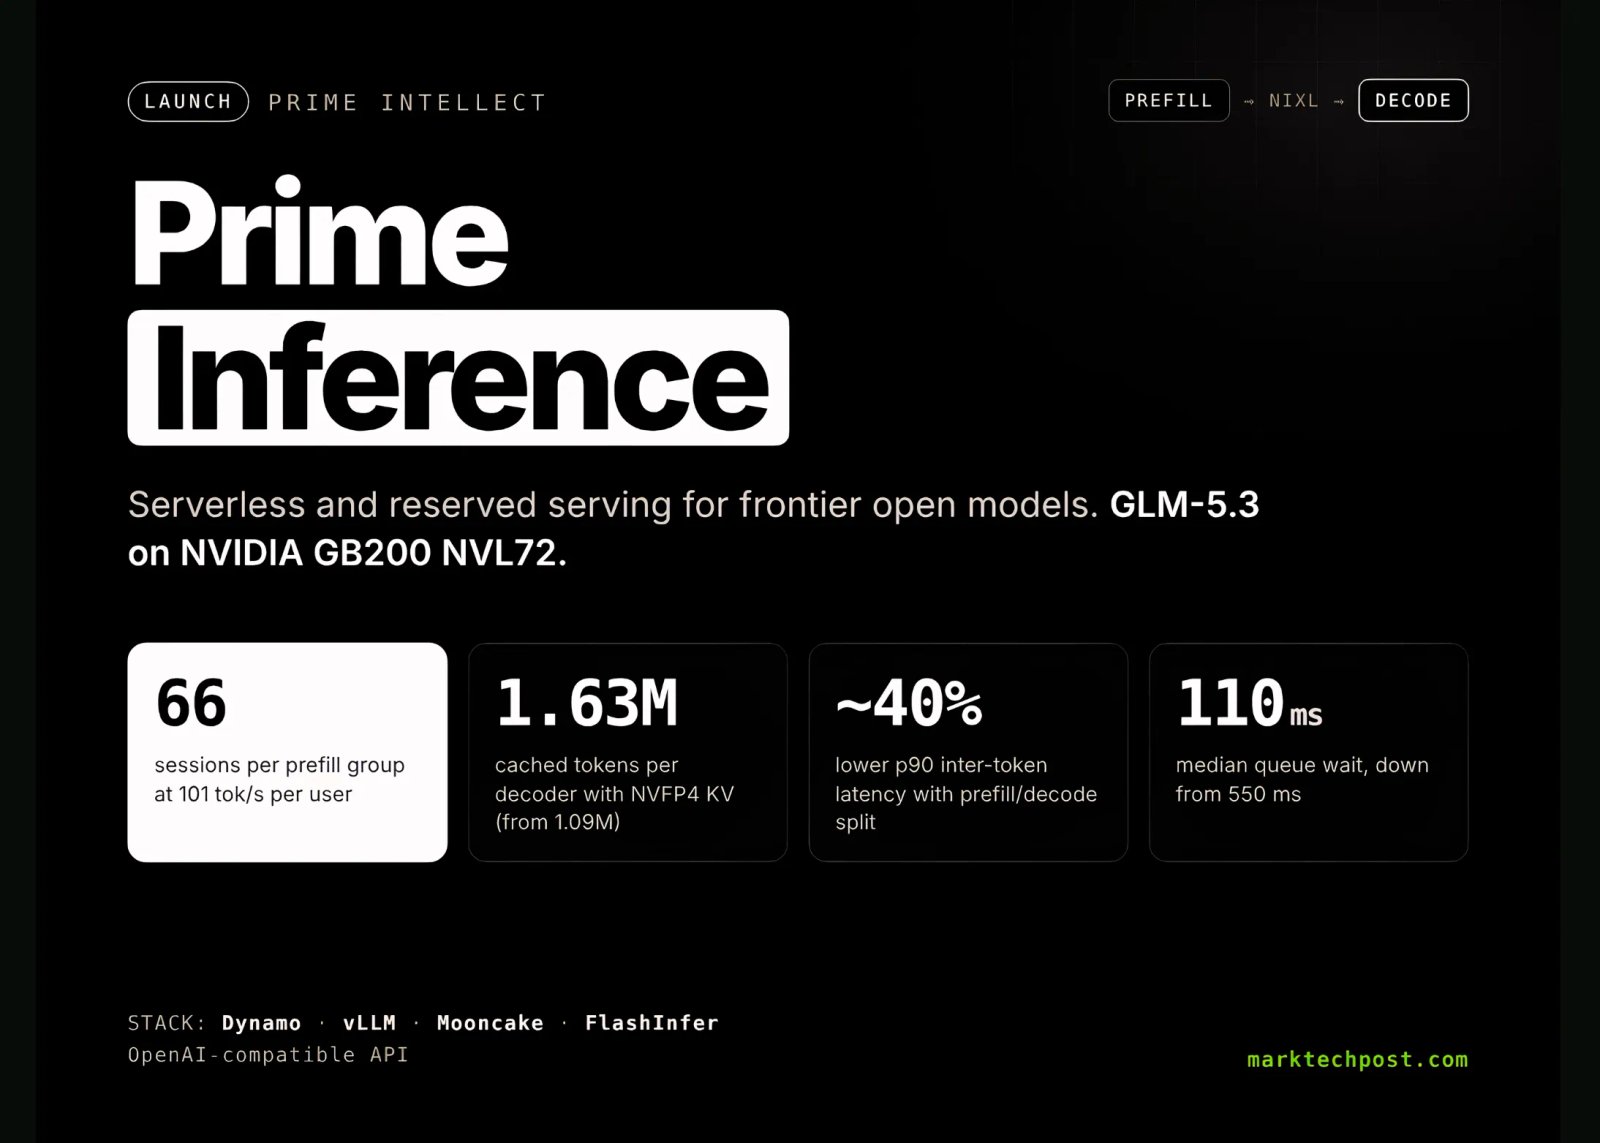
Prefill/decode disaggregation: Prefill and decode run on separate GPU groups. Dynamo handles routing, and vLLM runs the model on each group. Decoders pull computed KV through NIXL. Prime reports nearly 40% lower p90 inter-token latency in its tests.
Cache-aware routing:Dynamo’s KV-aware router weighs cached prefix overlap against queued work. Sessions stay on the same decoder between turns. Mooncake adds a second KV tier in host DRAM.
GLM-5.3 on GB200 NVL72: the numbers
The interactivity target was 100 end-to-end tokens per second per user. At that bar, a 1:4 prefill/decode ratio served the most users. It reached 66 sessions per prefill group at 101 tok/s per user and 100 output tok/s per GPU.
- DEP8 prefill topology: roughly 5x more usable prefix-cache capacity than TEP8 on the same hardware.
- Smaller prefill budget: halving tokens per step from 8K to 4K per GPU cut median queue wait from 550 ms to 110 ms. Median time to first token fell about 20%.
- NVFP4 KV compression: each MLA cache row shrank from 576 to 352 bytes. Cached tokens per decoder rose from 1.09M to 1.63M.
- Native sparse-MLA kernel: about 12.0 μs at 15 query tokens, versus 17.7 μs staged and 13.7 μs FP8. Prime notes this is workload specific.
- BLHNC KV layout: transfer descriptors fell from 19,559 to about 1,940. Mean transfer time dropped from 146 ms to 78 ms.
Agents fail when tool calls carry wrong names or broken arguments. Prime Intellect’s team contributed a structural-tag builder to Dynamo for GLM’s tool format. vLLM then uses xgrammar to mask tokens that violate the tool schema. The team also fixed parsing bugs, including < being decoded into < inside code.
Interactive explainer
0)$(‘n’+(i-1)).classList.remove(‘hot’);if(i>=5){busy=false;$(‘log’).textContent=(warm?’Done. Cache reuse kept time to first token short.’:’Done. Long prefill ran without stalling other users.’);return}
$(‘n’+i).classList.add(‘hot’);$(‘log’).textContent=(i+1)+’/5 ‘+m[i];p.style.transition=’width ‘+dur[i]+’ms linear’;p.style.width=((i+1)*20)+’%’;i++;setTimeout(step,dur[i-1]+250)}
setTimeout(step,30)};
/* 02 kv */
var kvMode=0;
function setKV(n){kvMode=n;if(n==0){pick(‘fp8′,’nv4’);$(‘sL’).style.flexBasis=”88.9%”;$(‘sL’).textContent=”512 latent: 512 B”;$(‘sS’).style.flexBasis=”0%”;$(‘sS’).textContent=””;$(‘sR’).style.flexBasis=”11.1%”;$(‘sE’).style.flexBasis=”0%”;$(‘bdesc’).textContent=”FP8: 1 byte per value. 512 + 64 = 576 bytes per row.”;$(‘bytesv’).textContent=”576 B”;$(‘capv’).textContent=”1.09M”;$(‘capf’).style.width=”66.9%”}
else{pick(‘nv4′,’fp8’);$(‘sL’).style.flexBasis=”44.4%”;$(‘sL’).textContent=”latent: 256 B”;$(‘sS’).style.flexBasis=”5.6%”;$(‘sS’).textContent=”32″;$(‘sR’).style.flexBasis=”11.1%”;$(‘sE’).style.flexBasis=”38.9%”;$(‘bdesc’).textContent=”NVFP4: 4 bits per latent value (256 B) + 1 FP8 scale per 16 values (32 B) + 64 B FP8 RoPE = 352 B.”;$(‘bytesv’).textContent=”352 B”;$(‘capv’).textContent=”1.63M”;$(‘capf’).style.width=”100%”}}
$(‘fp8’).onclick=function(){setKV(0)};$(‘nv4′).onclick=function(){setKV(1)};
/* 03 queue */
var qt=null;
function setB(n){var w=n==8?550:110;pick(n==8?’b8′:’b4′,n==8?’b4′:’b8’);$(‘qf’).style.width=(w/550*100)+’%’;$(‘qv’).textContent=w+’ ms’;$(‘qdesc’).textContent=n==8?’Big prefill steps let in-flight work fill the batch, so requests with cached KV already loaded still wait.’:’Halving the budget to 4K shortens each step. Ready requests start sooner, cutting median time to first token by roughly 20%.’;
var q=$(‘q’);q.innerHTML=”;for(var i=0;i<14;i++){var r=document.createElement(‘div’);r.className=”req”;q.appendChild(r)}
clearInterval(qt);var k=0,rate=n==8?520:110;qt=setInterval(function(){var c=q.children;if(k